
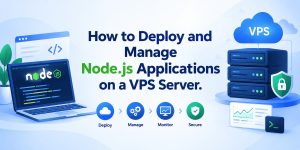
What is Node.js VPS server management?
Node.js VPS server management keeps a Node.js application running securely and reliably on a virtual private server. A VPS provides the Linux operating system, CPU, memory, storage, networking, and administrative access, while Node.js provides the runtime that executes the application’s JavaScript code. Server management connects these two layers by handling operating-system configuration, application processes, networking, security, monitoring, backups, updates, and incident response.
A production Node.js application needs more than a successful deployment. The application must survive process failures, receive traffic through the correct network path, use a supported Node.js release, expose only necessary services, maintain sufficient CPU and memory resources, and recover predictably after a server reboot. Node.js itself is a JavaScript runtime designed to run servers, web applications, command-line tools, and scripts.
Why does a Node.js application need a VPS?
A VPS gives a Node.js application dedicated operating-system resources and administrative control. Unlike shared hosting environments that restrict system-level configuration, a VPS normally gives the administrator control over services, firewall rules, packages, users, application processes, network ports, storage, and web-server configuration.
This control becomes important when an application requires a specific Node.js release, background workers, custom environment variables, WebSocket connections, scheduled jobs, private databases, reverse-proxy rules, or application-specific resource limits. A development team can therefore deploy the application according to its architecture instead of adapting the application to a heavily restricted hosting environment.
How do VPS and Node.js work together?
The VPS provides the infrastructure while Node.js provides the application runtime. The operating system runs the Node.js process, Node.js executes the application code, and a web server such as NGINX can receive public HTTP or HTTPS traffic before forwarding requests to the Node.js application.
A common production architecture places the Node.js process on a private local port such as 127.0.0.1:3000, while NGINX listens on public ports 80 and 443. NGINX then acts as a reverse proxy and forwards incoming requests to the application. NGINX officially supports reverse proxying through its proxy_pass functionality.
What does a production Node.js VPS architecture look like?
A production Node.js VPS commonly separates public traffic handling from application execution. The browser or API client connects to the server through HTTPS, NGINX terminates or passes through the TLS connection, NGINX selects the appropriate virtual host, and the reverse-proxy layer forwards the request to the Node.js process.
The application does not need to listen directly on a publicly accessible interface when NGINX handles external traffic. This arrangement reduces the number of application ports exposed to the Internet and gives the infrastructure team a central location for TLS configuration, request routing, connection handling, access controls, and traffic distribution.
NGINX determines the appropriate virtual server using the HTTP Host header and configured server_name values, which allows multiple domains or applications to share one server while maintaining separate routing rules.
How should you choose the Node.js version for production?
Production Node.js applications should use an Active LTS or Maintenance LTS release. The Node.js project explicitly recommends those release categories for production applications because they receive ongoing maintenance and security support. As of September 2026, Node.js 24 and 22 are listed as LTS branches, while Node.js 26 is listed as Current.
The infrastructure team should select the Node.js version based on the application’s framework and dependency compatibility rather than automatically installing the newest release. A version change can affect native modules, framework compatibility, package behavior, runtime APIs, and application startup. Production deployments should therefore test the selected Node.js version before changing an established environment.
How do you prepare a Linux VPS for Node.js?
A production VPS should start with controlled access, current system packages, firewall rules, and sufficient resources before application deployment. The administrator should create appropriate non-root administrative access, restrict unnecessary network services, configure SSH securely, establish firewall rules, and verify available CPU, memory, storage, and swap capacity.
Ubuntu’s current server security guidance recommends keeping the system updated, applying least-privilege access, using a firewall, and securing remote administration through SSH. Ubuntu Server also supports automatic security updates through unattended-upgrades, which is installed by default on current Ubuntu Server installations.
How do you deploy a Node.js application on a VPS?
Node.js application deployment requires transferring the application, installing compatible dependencies, configuring environment variables, and starting the application under a controlled process model. The application source normally resides in a dedicated directory owned by an appropriate service account rather than an unrestricted root account.
The deployment process should keep configuration separate from source code. Database credentials, API keys, encryption secrets, third-party credentials, and other sensitive values should come from protected environment configuration or a suitable secret-management system. Production deployments should also lock dependency versions through the project’s package-management files so that a later deployment does not unexpectedly install incompatible dependency versions.
How should you keep a Node.js application running after deployment?
A Node.js application needs a process-management strategy that can restart the application after failures and server reboots. Starting the application manually from an SSH session does not provide production process supervision because the application can terminate when the process exits, the session closes, or the server reboots.
Teams commonly use a process manager such as PM2 or a native systemd service. The important infrastructure requirement is not the choice of a particular tool but the resulting behavior: the application should start automatically when required, restart after an unexpected process failure, run with an appropriate operating-system user, expose predictable health information, and produce logs that administrators can inspect.
Why should NGINX sit in front of Node.js?
NGINX provides a controlled public-facing layer between Internet clients and the Node.js application. NGINX can receive HTTP and HTTPS requests, select the correct virtual host, forward requests to the application, manage connection behavior, and provide a central point for TLS and routing configuration.
NGINX documentation describes the reverse-proxy model as receiving a client request, passing it to another server, receiving the response, and returning that response to the client. Its upstream functionality can also distribute HTTP traffic across multiple application instances when the architecture requires horizontal scaling.
How does SSL protect a Node.js VPS application?
HTTPS encrypts communication between clients and the public server endpoint. In a production architecture, TLS commonly terminates at NGINX while the reverse proxy communicates with the Node.js application over a controlled local or private network connection.
The infrastructure team must maintain certificate validity, configure appropriate TLS settings, redirect unintended HTTP traffic where appropriate, and ensure that application-generated URLs and cookies correctly understand the HTTPS environment. NGINX supports SSL/TLS and SNI as part of its web-server capabilities.
How should you monitor CPU and memory on a Node.js VPS?
CPU and memory monitoring helps distinguish application problems from infrastructure saturation. A Node.js application can experience slow requests because of CPU-intensive JavaScript execution, memory pressure, excessive concurrent requests, inefficient database queries, external API delays, or insufficient VPS resources.
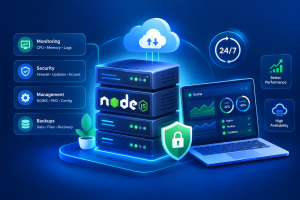
A useful monitoring system should track CPU utilization, available memory, swap activity, disk utilization, disk latency where available, network throughput, process state, application response time, HTTP status codes, and restart frequency. Infrastructure teams should establish historical baselines instead of treating a single CPU percentage as proof of a performance problem.
Memory pressure deserves particular attention because Linux can reclaim filesystem cache when necessary, meaning high memory utilization alone does not always indicate an outage condition. Available memory, swap activity, process-level consumption, and application behavior provide better diagnostic context.
How should you monitor Node.js application health?
Application monitoring should measure service availability in addition to server resource utilization. A VPS can show healthy CPU and memory metrics while the Node.js application returns HTTP 500 errors, fails database connections, becomes unresponsive, or repeatedly restarts.
A production monitoring design should therefore combine infrastructure checks with application-level checks. An external monitor can verify the public HTTPS endpoint, while server-side monitoring can track the Node.js process, NGINX status, disk capacity, certificate expiration, and critical system services.
How do you troubleshoot a Node.js application that suddenly stops responding?
A failed Node.js application should be investigated from the request path inward rather than by restarting the server immediately. The investigation should determine whether DNS resolves to the correct server, whether NGINX accepts the request, whether NGINX can reach the Node.js process, whether the application process remains alive, whether the application can reach its database or external dependencies, and whether the VPS has sufficient resources.
This layered approach prevents infrastructure teams from masking the root cause with repeated restarts. For example, an NGINX 502 response can indicate that the reverse proxy cannot successfully communicate with the upstream application, so the investigation should examine the upstream process and connection path rather than treating the HTTP status itself as the root cause.
What causes common NGINX 502 errors with Node.js?
A Node.js application commonly produces an NGINX 502 response when the reverse proxy cannot obtain a valid response from the configured upstream. Possible causes include a stopped Node.js process, an incorrect application port, a process listening only on an unexpected interface, connection refusal, application startup failure, resource exhaustion, or an incorrectly configured upstream address.
NGINX’s proxy documentation defines proxy_pass as the mechanism used to specify the upstream protocol, address, and optional port, while proxy_connect_timeout and proxy_read_timeout control different stages of communication with the upstream server.
How should you manage Node.js application restarts?
Application restarts should follow a controlled policy instead of relying on manual intervention. A process manager or system service should restart a process when it terminates unexpectedly while preserving enough information for administrators to determine why the process failed.
Automatic restart alone does not solve an application defect. If an application crashes every few seconds because of a configuration error, uncontrolled automatic restarting can create a restart loop and hide the underlying failure. Effective server management therefore combines restart policies with process monitoring, log retention, alerting, resource limits, and application health checks.
How do backups protect a Node.js VPS?
A VPS backup strategy must protect application data, configuration, databases, and deployment information rather than only the operating-system disk. A useful recovery plan should identify what the application requires to rebuild the environment, including source or deployment artifacts, environment configuration, database data, uploaded files, reverse-proxy configuration, SSL-related information where appropriate, and scheduled jobs.
Backups should also have a defined retention policy and restoration procedure. A backup that has never undergone a restoration test cannot demonstrate that the business can recover from corruption, accidental deletion, ransomware, failed upgrades, or infrastructure loss.
How should you secure a Node.js VPS?
VPS security requires controls at the operating-system, network, application, and dependency layers. The operating system should receive security updates, administrative access should follow least privilege, unnecessary ports should remain closed, SSH access should be controlled, and the application should avoid running with unnecessary root privileges.
Node.js dependencies also form part of the attack surface. A secure deployment process should review dependency updates, remove unused packages, monitor security advisories, and test dependency changes before production deployment. Ubuntu’s security guidance specifically recommends regular system updates, least-privilege access, firewall configuration, and secure SSH administration.
How should you manage Node.js updates without causing downtime?
Node.js upgrades should be treated as controlled production changes rather than routine package replacements. The administrator should first identify the application’s current runtime and dependency requirements, test the target Node.js version in a staging environment, verify application startup and critical workflows, and then schedule the production change according to the application’s availability requirements.
This becomes especially important because Node.js releases move through different support stages. The official release schedule currently lists Node.js 24 and 22 as LTS branches and Node.js 26 as Current, demonstrating why infrastructure teams should track the Node.js release lifecycle rather than allowing production systems to remain indefinitely on an unsupported runtime.
What happens when a VPS runs out of memory?
Memory exhaustion can cause application instability, process termination, and service degradation across the VPS. When available memory becomes critically low, Linux may reclaim caches, increase swap activity, or invoke the out-of-memory mechanism when it cannot satisfy further allocations.
For Node.js workloads, administrators should examine application memory growth, garbage-collection behavior, concurrent workload, database connections, worker processes, and other services sharing the VPS. Increasing VPS RAM can address a genuine capacity problem, but it should not replace investigation into a memory leak or uncontrolled workload.
How can server management improve Node.js application reliability?
Server management improves reliability by continuously controlling the infrastructure conditions that Node.js depends on. The management layer maintains operating-system updates, network access, process supervision, reverse-proxy configuration, resource monitoring, backups, security controls, certificate management, and incident response.
This distinction matters because developers typically focus on application behavior while infrastructure teams focus on the environment that executes the application. A production Node.js service requires both disciplines. A correctly written application can still become unavailable when its disk reaches capacity, its certificate expires, its process crashes, its VPS exhausts memory, or its reverse proxy points to the wrong port.
What does a real-world Node.js VPS failure look like?
A realistic Node.js outage often involves several small infrastructure failures rather than one obvious defect. Consider a production API running on a Linux VPS behind NGINX where the application initially handles approximately 120 requests per second with 4 GB of available memory. A new application release introduces higher memory consumption, while application logs and temporary files continue accumulating on the same VPS.
Over several days, available memory falls, swap activity increases, and disk utilization approaches capacity. Node.js response times increase because the application spends more time under memory pressure, while NGINX begins reporting upstream failures when the Node.js process becomes unstable. Restarting Node.js temporarily restores service, but the underlying memory and storage conditions remain.
The infrastructure solution should address the complete failure chain rather than only restarting the application. The team can separate application and system logs, establish disk-capacity alerts, monitor process memory, enforce sensible log retention, review the application’s memory behavior, verify swap configuration, and introduce application health monitoring. If traffic continues growing, the architecture can move from a single Node.js process toward multiple application instances behind NGINX. NGINX supports upstream server groups and HTTP load balancing for this type of architecture.
The important lesson is that Node.js server management is an ongoing operational function, not a one-time deployment task. The deployment makes the application available; monitoring, security, maintenance, capacity management, backups, and incident response keep it available.
When should a business use managed Node.js VPS support?
Managed Node.js VPS support becomes valuable when a business needs continuous infrastructure administration without maintaining a dedicated server-operations team. A managed infrastructure provider can take responsibility for server monitoring, operating-system maintenance, security configuration, Node.js runtime management, NGINX configuration, SSL administration, backups, resource analysis, incident response, and deployment-related infrastructure issues.
For development teams, this model allows developers to concentrate on application features while infrastructure specialists maintain the underlying Linux environment. For hosting providers and technology companies, outsourced server management can also provide additional operational capacity when internal teams need coverage outside normal business hours.
Organizations operating multiple servers may require 24/7 server management services and server monitoring services 24/7 when application availability directly affects customer transactions, APIs, SaaS platforms, or business operations.
How can outsourced server management support Node.js environments?
Outsourced server management can extend a development team’s infrastructure capability without requiring the company to build every operational function internally. A provider can monitor server health, investigate application availability issues, manage Linux updates, troubleshoot NGINX and networking problems, review resource consumption, maintain backup procedures, and coordinate infrastructure changes with developers.
For technology companies serving their own customers, white label server support can also allow the company’s support operation to extend its infrastructure capabilities without exposing the underlying third-party operational arrangement to end customers, subject to the applicable service agreement and disclosure requirements.
What should a Node.js VPS management checklist measure?
A useful Node.js VPS management program measures application availability, server health, security state, capacity, and recovery readiness. The exact thresholds should depend on the application’s workload and business requirements rather than arbitrary universal percentages.
| Area | What to Monitor |
|---|---|
| Application | Availability, HTTP errors, response time, process restarts |
| Node.js | Runtime version, process state, memory behavior, dependency health |
| CPU | Utilization, load, sustained saturation |
| Memory | Available memory, swap activity, process consumption |
| Storage | Disk usage, inode usage, growth rate |
| NGINX | Availability, upstream failures, HTTP status distribution |
| Network | Traffic volume, connection behavior, packet errors |
| Security | Updates, SSH access, firewall rules, exposed services |
| SSL | Certificate validity and expiration |
| Backup | Backup success, retention, restoration testing |
| Recovery | Application restart, VPS recovery, configuration restoration |
What is the difference between deploying Node.js and managing Node.js?
Deployment makes a Node.js application available, while management keeps the application operational over time. Deployment normally covers application transfer, dependencies, environment configuration, process startup, DNS, reverse-proxy configuration, and SSL.
Management continues after deployment. It includes monitoring, security updates, runtime lifecycle management, resource optimization, backup verification, certificate renewal, incident response, performance analysis, and recovery planning. This distinction explains why a successful deployment does not automatically create a production-ready operating environment.
How can cloud infrastructure management extend a Node.js VPS?
Cloud infrastructure management becomes important when a Node.js application grows beyond a single-server architecture. A business may eventually separate the application tier from the database, introduce dedicated caching, add background workers, distribute traffic across multiple VPS instances, or move components into a public cloud environment.
At that stage, cloud infrastructure management services can cover resource provisioning, networking, monitoring, security, backup architecture, scaling, and operational governance across multiple infrastructure components. The same principles remain relevant whether the application runs on one VPS or across a larger distributed environment.
What should you verify before putting Node.js into production?
A Node.js production environment should have a documented deployment, monitoring, security, backup, and recovery process before receiving business-critical traffic. The application should run on a supported Node.js release, use controlled process supervision, sit behind an appropriately configured reverse proxy, use HTTPS, restrict administrative access, maintain current security updates, monitor application and server health, and have tested backups.
A production environment should also have a defined ownership model. Developers should know who handles application defects, while infrastructure administrators should know who handles operating-system, networking, storage, security, and availability incidents. Clear ownership reduces the time spent transferring incidents between teams.