
Quick answer:
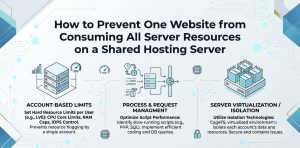
One resource-heavy website can degrade performance across a shared hosting server when its workload competes for CPU, memory, storage I/O, database capacity, or web server workers. Hosting administrators can prevent this by identifying the responsible workload, enforcing account-level or per-domain resource limits, optimizing application execution, and monitoring resource consumption. Effective isolation protects neighboring websites without treating every traffic spike as a reason to upgrade the server.
Which Server Resources Must Administrators Protect?
CPU, physical memory, disk I/O, process counts, concurrent application requests, and database capacity require separate monitoring because each resource creates a different failure pattern. CPU saturation increases execution delays, memory exhaustion can trigger allocation failures or out-of-memory events, and storage congestion delays database and application reads or writes. Excessive PHP workers can consume memory while competing for CPU, whereas slow database queries can keep application workers occupied even when CPU utilization remains moderate.
Account-level isolation controls the resources attributed to a hosting customer, but it does not automatically isolate every domain inside that account. When several websites share one account, a resource-intensive domain may consume the account’s allowance before its sibling websites can complete their work. Administrators must therefore determine whether the bottleneck exists at the domain, account, database, web server, or physical-host level before choosing a containment strategy.
How Do You Identify the Website Causing High Resource Usage?
Accurate resource attribution is the first step toward preventing a shared hosting incident from affecting unrelated customers. Administrators should correlate CPU usage, resident memory, process ownership, PHP execution, database activity, and domain access patterns over the same time window. A server-wide CPU graph identifies the symptom, but per-account or per-domain metrics help identify the workload responsible for it.
On a cPanel server, WHM’s resource usage reports and CloudLinux LVE Manager can reveal which accounts approach their limits and which resource faults occur. Process inspection can identify repeated PHP workers or unexpectedly long-running scripts, while web access logs can reveal whether the same endpoint receives a high volume of requests. These signals should be correlated rather than interpreted independently because a busy account may reflect legitimate traffic, inefficient code, automated imports, or malicious requests.
How Should You Distinguish CPU Saturation from Memory and Disk I/O Problems?
CPU saturation occurs when runnable processes compete for available processing time, while memory pressure occurs when applications demand more physical memory than the system can comfortably provide. Disk I/O congestion can delay application and database operations even when CPU utilization appears low. Administrators should compare CPU utilization and I/O wait with available memory, swap activity, storage latency, process counts, and database response times to determine which resource limits application throughput.
A useful diagnostic approach compares the time of a reported slowdown with historical metrics and the affected account’s resource faults. If CPU usage rises alongside PHP worker activity, investigate expensive scripts and request patterns. If memory rises as worker counts increase, calculate the memory demand of concurrent workers and review PHP-FPM pool settings. If database latency and I/O wait increase together, inspect storage performance, query execution, and background jobs before increasing CPU or memory allocations.
How Do CloudLinux LVE Limits Prevent Resource Abuse?
CloudLinux Lightweight Virtual Environment (LVE) limits constrain the resources available to individual hosting accounts on supported CloudLinux systems. Administrators can configure CPU, physical memory, disk I/O, I/O operations per second, process counts, and entry processes according to the hosting plan. These controls prevent a single account from consuming unlimited shares of the resources managed by LVE, although they do not remove every server-wide bottleneck or replace application troubleshooting.
In a cPanel environment, administrators can review LVE Manager and apply limits that match the account’s service tier and the server’s capacity. A limit should provide enough headroom for normal traffic and expected bursts without allowing one account to starve neighboring customers. If administrators set limits too low, legitimate websites may experience throttling or application errors. If they set limits too high, the account may still create pressure on shared infrastructure. The correct configuration therefore depends on measured workloads, resource capacity, and the service commitment offered to customers.
What Happens When a Website Reaches Its LVE Limits?
An LVE resource fault indicates that a workload reached a configured limit; it does not, by itself, prove that the application is defective or compromised. CPU or I/O limits can throttle execution, while memory or process restrictions may prevent new work from starting successfully. Entry-process limits can cause HTTP 508 responses in applicable CloudLinux configurations, and process or memory exhaustion may contribute to HTTP 500 or 503 errors. Administrators should verify the relevant fault counters and application logs before attributing an error to a specific limit.
The appropriate response is to identify why the website reached the limit and determine whether the workload is expected. A short traffic surge may require temporary observation and caching improvements, while recurring faults may indicate inefficient application code, excessive concurrency, or insufficient plan capacity. Raising every limit immediately can hide the cause and transfer the problem to the wider server, so changes should follow evidence and include post-change monitoring.
How Can You Isolate One Website from Other Domains in the Same Account?
Per-domain resource isolation addresses a limitation of account-level controls: multiple domains can share one account’s resource allowance. CloudLinux Isolates supports domain-level filesystem isolation through CageFS and, on supported configurations, per-domain resource isolation through LVE. With per-domain LVE limits enabled and the required prerequisites satisfied, administrators can account for and restrict the CPU, memory, I/O, and process consumption of individual websites. .
This distinction matters for agencies, resellers, and customers who operate several websites under one cPanel account. A busy ecommerce site may require different resource controls from a low-traffic corporate site, even when both share the same account. Administrators should verify operating system compatibility, installed packages, control-panel integration, and the per-domain isolation prerequisites before relying on these controls. Per-domain limits remain bounded by the parent account and reseller allocations, so assigning a larger domain limit cannot create resources that the parent plan does not provide.
Where per-domain isolation is unavailable, separating high-demand websites into individual accounts can improve attribution and make account-level limits more effective. For workloads that require sustained high concurrency, custom services, or substantial database capacity, a VPS or dedicated environment may offer a more suitable isolation boundary than shared hosting.
How Should You Optimize PHP-FPM Without Creating More Resource Pressure?
PHP-FPM manages PHP worker processes, and its pool configuration directly influences the amount of work an application can execute concurrently. A pool that permits too many workers can exhaust memory, while a pool with too few workers can create request queues and increase response latency during traffic peaks. Administrators should size worker capacity from measured memory consumption, available RAM, expected concurrency, and the memory requirements of other services running on the server.
For example, if 20 PHP workers each consume an average of 60 MB of resident memory, their combined worker footprint is approximately 1.2 GB. This estimate excludes web server processes, database memory, operating system overhead, shared memory, and other applications, so it cannot be treated as a safe pool allocation by itself. Measure real worker usage under representative load, retain operating-system headroom, and verify whether the hosting account’s memory limit can accommodate the selected concurrency.
PHP OPcache can reduce repeated script compilation, while full-page caching can avoid executing PHP for eligible public requests. Object caching can reduce repeated database reads, and a CDN can offload suitable static assets from the origin. These mechanisms address different costs: a CDN does not eliminate expensive uncached PHP requests, and object caching does not fix every slow query. Administrators should select caching layers based on the workload and validate authentication, personalized content, checkout, and cache invalidation behavior before deploying them broadly.
How Do You Reduce Database Contention from a Resource-Heavy Website?
Database contention occurs when queries, locks, connections, or storage operations prevent other work from progressing efficiently. A website can consume substantial server resources through repeated unindexed queries, inefficient joins, oversized result sets, excessive connection creation, or background jobs that update large tables. Administrators should identify the queries responsible for latency, review execution plans and indexes, and measure connection usage before increasing database connection limits.
Increasing the maximum number of database connections without examining query behavior can increase memory demand and concurrency pressure rather than improve throughput. A better strategy is to eliminate unnecessary queries, reduce repeated reads with appropriate caching, limit connection lifetimes, and schedule heavy imports or reporting jobs to avoid peak traffic. Where multiple customers share a database service, database-level monitoring and workload controls are also necessary because operating-system account isolation alone may not fully protect the database from competing queries.
How Can You Detect Bots, Traffic Spikes, and Compromised Scripts?
High request volume can result from legitimate visitors, search crawlers, API clients, aggressive bots, or malicious activity, so administrators should validate traffic patterns before blocking sources. Review request frequency, response codes, requested paths, user agents, source addresses, and the timing of CPU or PHP worker spikes. Repeated requests to login endpoints, expensive search pages, XML-RPC endpoints, or application APIs may warrant rate limiting or further investigation, but no single pattern proves an attack.
When a compromise is possible, inspect unexpected PHP files, modified application code, unauthorized cron jobs, suspicious outbound connections, and recently changed credentials. A high-resource process may be executing a legitimate but inefficient task, or it may be running unauthorized code; the distinction requires evidence. Apply a web application firewall, CDN-based rate controls, or application-specific throttling when appropriate, while preserving legitimate traffic and collecting enough information to understand the incident.
How Do Cron Jobs and Background Workers Cause Repeated Resource Spikes?
Scheduled tasks can create recurring CPU, memory, and storage spikes when they overlap, run too frequently, or process more data than the server can handle. Website imports, backup routines, search indexing, email processing, and application maintenance jobs can compete with live requests if administrators schedule them without considering runtime and concurrency. A task that normally takes ten minutes but runs every five minutes may create overlapping executions and an accumulating workload.
Administrators should review scheduled task frequency, execution duration, failure retries, and duplicate jobs. Use locking or queue mechanisms where appropriate to prevent overlapping work, and schedule resource-intensive maintenance outside peak periods when service requirements permit. Disabling every cron job is not a reliable solution because some applications depend on scheduled tasks for security updates, billing, notifications, and routine maintenance.
How Should Hosting Providers Monitor Resource Usage Before Customers Notice?
Proactive monitoring combines server-wide metrics with account-level or domain-level measurements so administrators can detect both capacity problems and individual resource abuse. Useful signals include sustained CPU utilization, available memory, swap activity, disk latency, I/O throughput, process counts, entry-process usage, database response time, and HTTP error rates. On CloudLinux systems, LVE usage and fault metrics provide additional evidence about whether an account is approaching its configured resource limits.
Monitoring alerts should reflect sustained pressure and the service’s actual limits instead of treating every short-lived spike as an incident. For example, a hosting team might alert when an account repeatedly reaches its CPU or entry-process limit during normal traffic, then correlate those events with application latency and HTTP errors. The exact thresholds should be established from baseline measurements and service objectives, not presented as universal values. Retaining historical data also helps distinguish a recurring application problem from an unusual traffic event or a wider infrastructure bottleneck.
What Does a Production Resource-Isolation Incident Look Like?
A resource-isolation incident should be resolved by correlating workload evidence with application behavior, not by raising every hosting limit. Consider the following illustrative production-style scenario, which demonstrates a diagnostic method rather than reporting a verified ActSupport customer incident. A shared server hosts several WordPress websites, and one ecommerce domain begins generating long response times during a product import. Server monitoring shows elevated PHP worker memory consumption, database latency, and increasing request queues, while unrelated sites begin returning intermittent errors.
The administrator compares the affected domain’s request volume, PHP worker usage, database query timings, and account-level LVE faults. The investigation identifies overlapping import jobs and expensive uncached product queries as the main contributors. The team prevents overlapping jobs, optimizes the slow queries, enables appropriate caching, and applies resource limits supported by the hosting configuration. The administrator then verifies that database latency and request queues have recovered and checks neighboring websites for continuing errors. The team records before-and-after measurements rather than claiming an arbitrary percentage improvement.
When Should You Upgrade a Hosting Plan Instead of Tightening Limits?
A hosting upgrade is appropriate when a website consistently reaches reasonable resource limits under normal, optimized workloads. Administrators should first determine whether the bottleneck comes from inefficient code, abnormal traffic, storage performance, database contention, or genuine capacity demand. If the workload legitimately needs more CPU, memory, concurrency, or database capacity than the current plan provides, a higher tier or isolated VPS may deliver a better customer experience than repeatedly throttling the application.
Hosting providers should also consider the wider capacity of the physical server. Increasing a customer’s allowance is not safe if the host lacks sufficient spare CPU, memory, storage throughput, or database capacity to support the change. Reseller limits and parent-account allocations must remain consistent with the underlying service plan. Capacity planning should account for peak concurrent demand, operational headroom, and the performance commitments offered to customers rather than simply adding together the maximum limits of every account.
How Does Managed Server Support Help Prevent Recurring Resource Incidents?
Managed server support helps hosting providers identify recurring resource bottlenecks, maintain isolation policies, optimize service configurations, and investigate incidents before they affect more customers. A structured operational process combines monitoring, capacity planning, application troubleshooting, security checks, and post-incident verification. Providers managing multiple customer environments may also use outsourced technical support services to extend technical coverage without assigning every investigation to their internal team.
ActSupport’s server management approach should connect these operational controls to measurable service outcomes, including fewer repeated resource incidents, clearer root-cause analysis, and better visibility into account-level performance. For hosting companies, agencies, and infrastructure teams, the goal is to keep individual workloads within appropriate boundaries while maintaining stable performance for the wider platform.
Frequently Asked Questions About Shared Hosting Resource Management
How can I stop one website from using all the CPU on a shared server?
Per-account CPU limits can restrict how much processing capacity a hosting account consumes on supported platforms. Administrators should identify the responsible scripts and requests, review resource faults, optimize expensive operations, and use per-domain limits where the hosting environment supports them. CPU limits contain the workload, while application optimization addresses the underlying cause.
Why does one website slow down other websites on the same hosting account?
Websites under the same account may share CPU, memory, process allowances, storage I/O, and database services. If one domain consumes the account’s available resources, its sibling websites may experience slower execution or errors. Per-domain isolation or separate hosting accounts can reduce this risk when configured and supported appropriately.
What is the difference between CloudLinux LVE and per-domain isolation?
CloudLinux LVE provides resource controls for hosting environments, commonly at the account level. CloudLinux Isolates adds domain-level filesystem isolation and supports per-domain resource limits on compatible configurations. Per-domain resource limits require the appropriate prerequisites and remain bounded by the parent account’s allocation.
Can increasing PHP-FPM workers fix high CPU usage?
Increasing PHP-FPM workers can improve concurrency when the pool is too small, but it can also increase memory demand and CPU contention. Administrators should measure worker utilization, memory consumption, queueing, and application execution time before changing pool settings. Caching and query optimization may improve throughput more safely than increasing worker counts.
When should a shared hosting website move to a VPS?
A VPS becomes worth considering when an optimized website repeatedly needs more CPU, memory, concurrency, or database capacity than its hosting plan can provide. A VPS can offer greater resource allocation and configuration control, but administrators must still monitor usage and secure the environment. Moving to a VPS does not automatically fix inefficient code or excessive traffic.